The stack view
The rule: a component nobody scanned is not a healthy component.
Architecture diagrams go out of date the week they're drawn, and code-health results live in a dozen tools nobody checks together. The Stack view derives the map from the running system and puts every scanner's latest answer on the box it belongs to, so the picture is current and the gaps show.
Why it matters
Where the risk is, by component: security findings, complexity hot spots, unfinished code, and which parts nobody has checked at all.
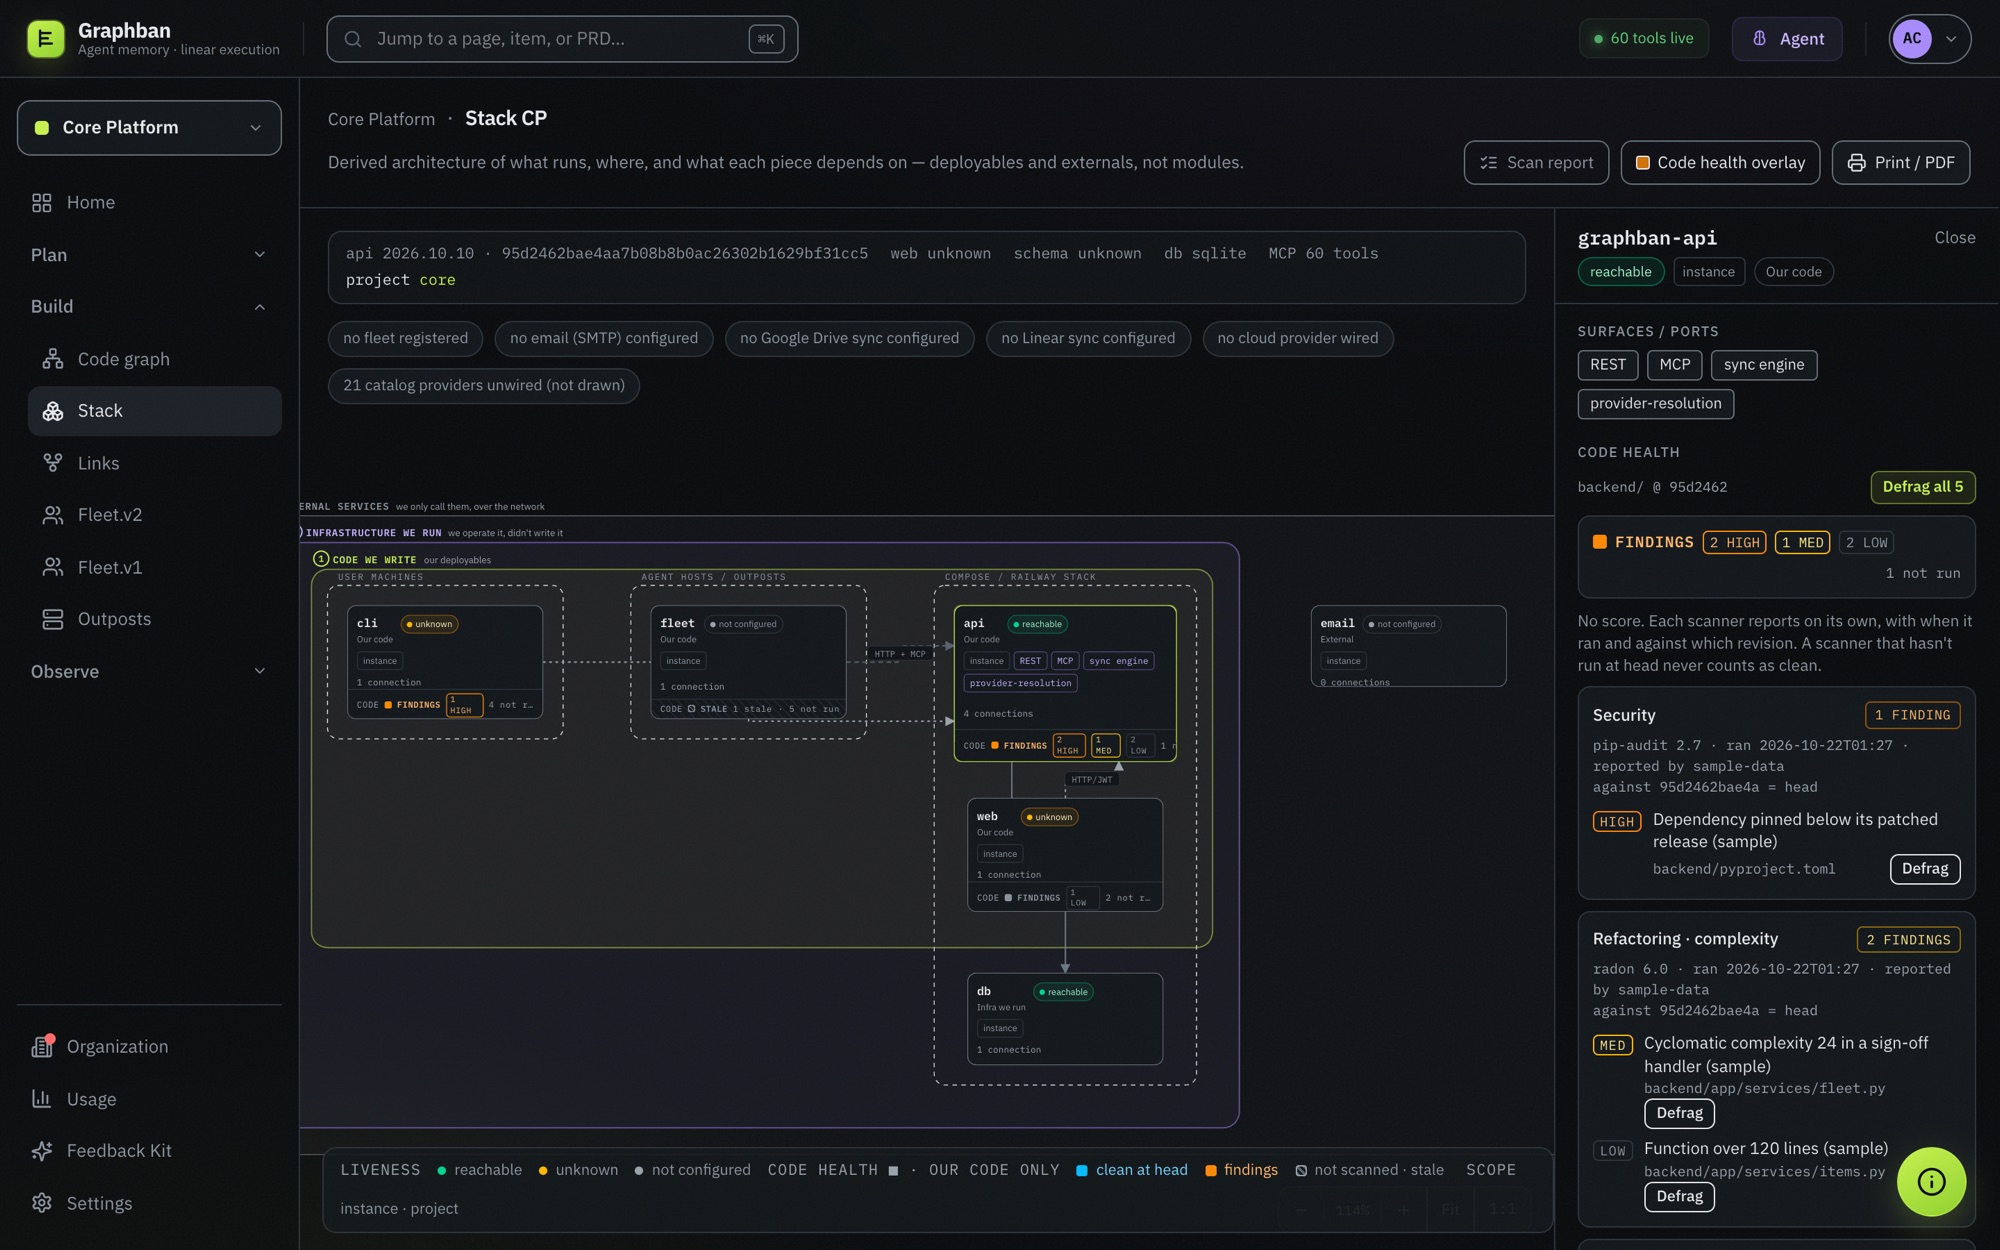
What runs where and what talks to what, before touching it. Click a box for its surfaces, its connections and every finding, with the file.
Tech debt stops being a vague backlog. One click turns a finding into a card on the board, where the fleet picks it up and it goes through review like any other work.
The map
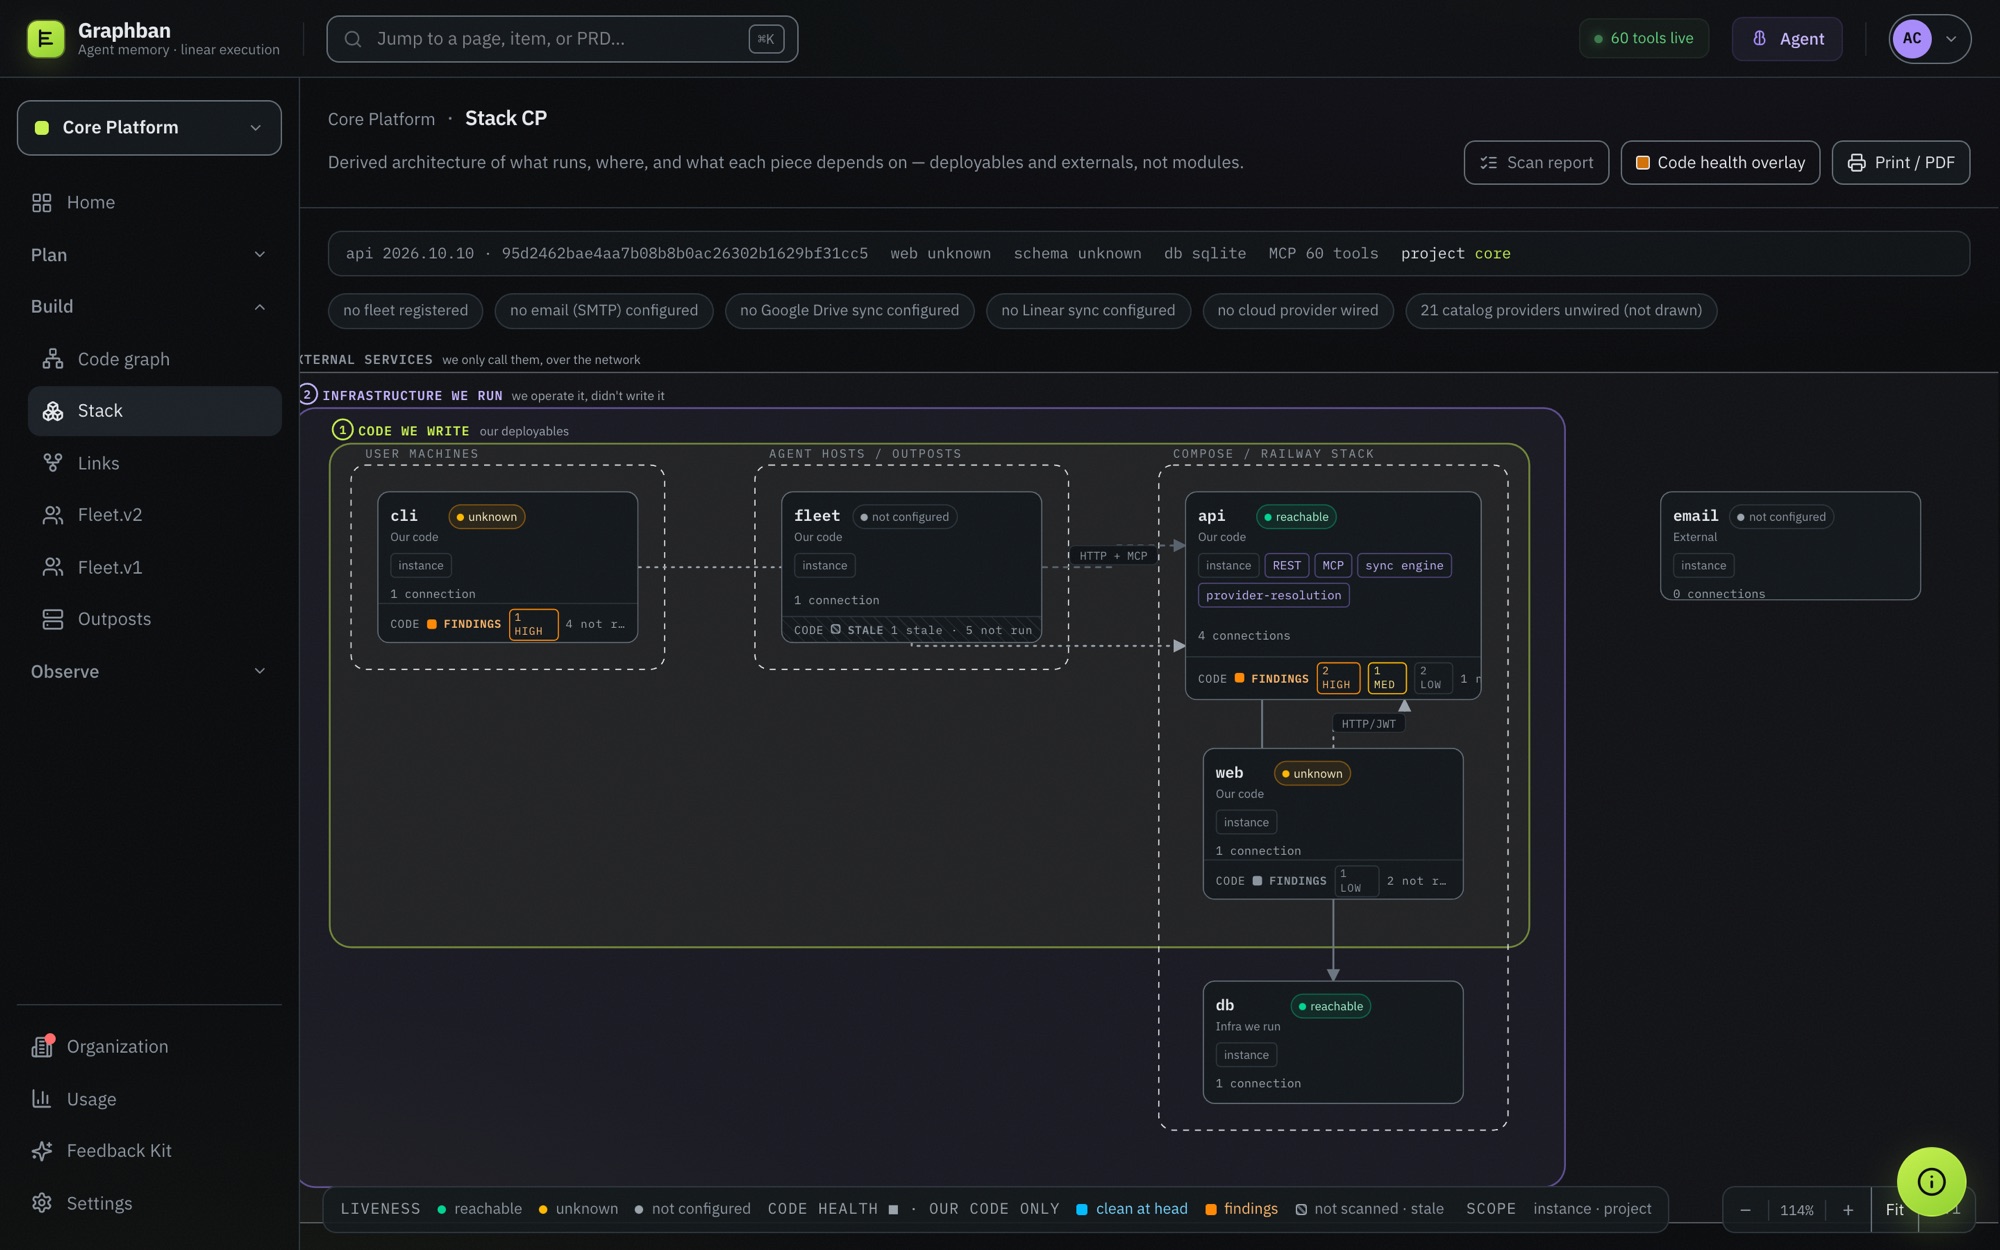
Nothing is placed by hand. The layout is a function of the topology the API reports, so when the system changes, the picture does too.
Your deployables, grouped by where they run: user machines, agent hosts and outposts, and the compose or hosted stack.
What you operate but didn't write, such as the database, nested around your code.
What you only call over the network, in its own column, so the boundary of ownership is visible.
Above the canvas, every absence gets a chip: no fleet registered, no email configured, no Linear sync, and how many catalogued providers are unwired. A diagram that only draws what exists makes a half-configured system look finished.
The health overlay
Each component carries seven categories. A finding records its severity, file, scanner and version, and the commit it was scanned against.
| Category | What it tells you | Fed by |
|---|---|---|
| Security | Vulnerable dependencies and risky code | pip-audit, npm audit, osv-scanner, bandit, semgrep, trivy |
| Refactoring · complexity | Hot spots: high cyclomatic complexity, oversized functions | radon, ESLint complexity |
| Partial implementation | Stubs and placeholders that shipped | a stub scan |
| Dead code | Functions, exports and files nothing uses any more | vulture, knip, ts-prune |
| Coverage | How much of the component the code map describes, and whether that description is stale | the code graph, built in |
| Tests | Whether the suite ran at the running commit, with passed, failed and skipped counts, and each failing test as a finding | pytest, vitest, jest, any JUnit report |
| Open work | Cards on the board that touch this component | the tracker, built in |
No score
There is no health score to game. Each category is in exactly one of four states, and the last two are never drawn as the first.
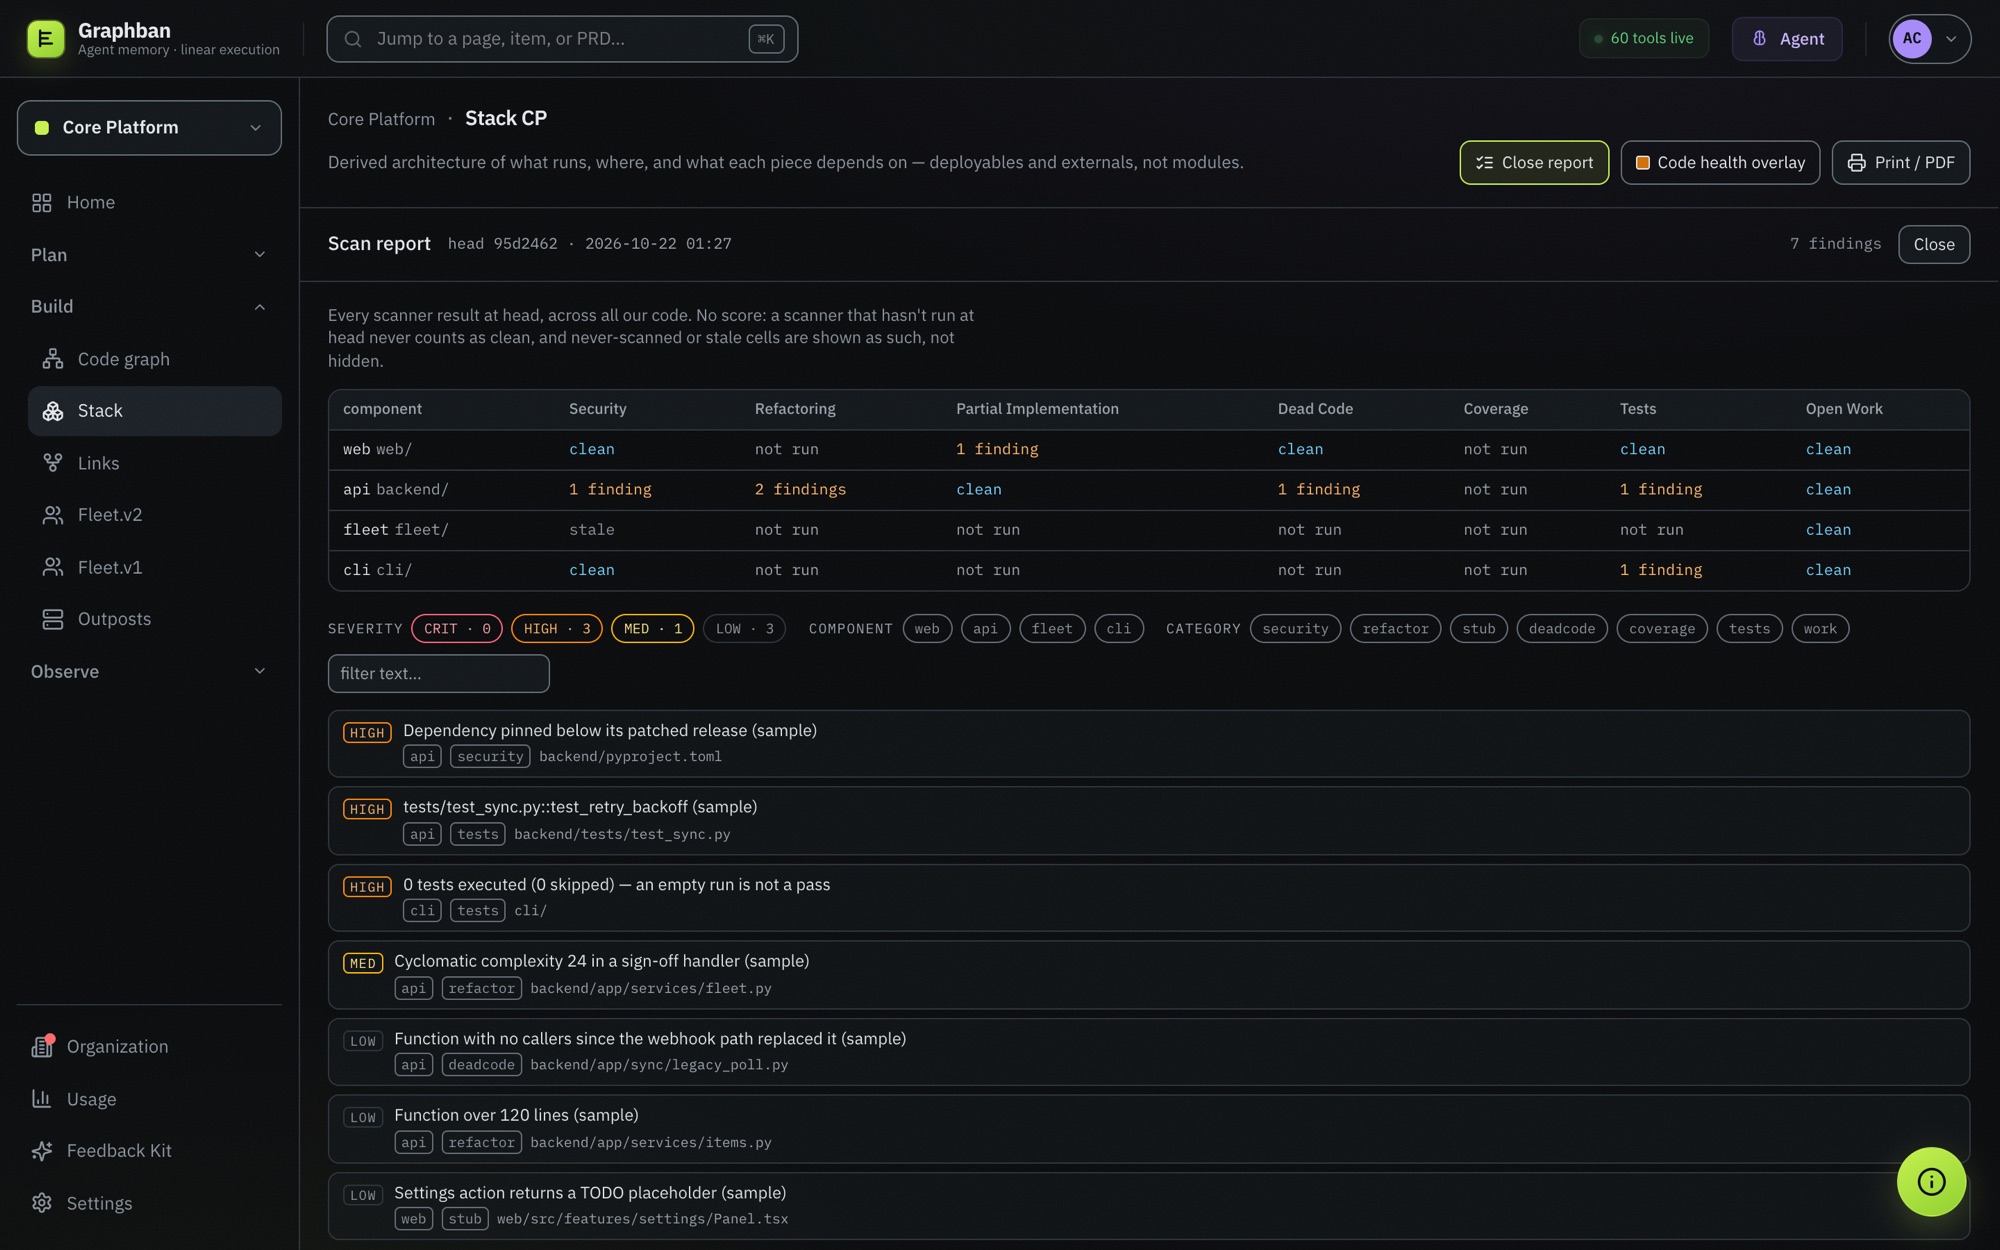
A component only rolls up clean when the result covers its whole tree. One clean file says nothing about the rest. That's why, in the screenshot above, fleet reads stale: its only scan predates the running commit. And cli shows a high finding even though nothing failed, because its test run executed zero tests. An empty run is not a pass, so it is recorded as one.
The scan report
Every component against every category, then every finding, filterable by severity, component, category and text. "Not run" and "stale" are cells, not blanks.
Defrag
Every finding has a Defrag button that files it as a card on the board, tagged as tech debt. Defrag all files every unfiled finding on a component at once.
Where the results come from
Graphban never runs a scanner. An agent working in your repo runs the tools you already trust and reports the results, the same way it describes code for the graph. CI can post them too, over a key-authenticated REST endpoint.
Coverage and open work need no scanner at all: they come from the code graph and the board. How the code graph is built →